
Breaking a zk-SNARK library: gnark's classic-GLV soundness failure
A constraint-valid scalar split, an incomplete addition, and a Groth16 proof for an off-curve result in gnark's BLS12-381 and BW6-761 gadgets.
Whoopwhoop new GHSA alert: GHSA-4g5f-3gmm-9q87
Here, we’re gonna follow my classic-GLV finding through one BLS12-381 case in detail. The other cases I reproduced follow the same pattern; the advisory also covers independent findings.
Okeyyy, ready? Then let’s start with a lil’ context.
I started looking at gnark’s scalar-multiplication code after reading GHSA-7fx8-hmgc-82jp , an earlier gnark advisory about a fake-GLV soundness issue discovered by Certora. It listed BLS12-381 as unaffected by that bug. That curve’s classic-GLV path computes the result in-circuit. If those names are unfamiliar, we’ll go through both methods and what went wrong in that advisory below.
Soooo yea’, I got the target to fight with: the classic-GLV implementation. My goal: to see how far I could push the values accepted by the circuit and to observe if an off-curve point could be accepted.
gnark and classic GLV#
gnark
is a Go library for writing zk-SNARK circuits and proving them with backends such as Groth16 or PLONK. A circuit’s Define method looks like ordinary Go, but it runs at compile time over symbolic variables. Calls such as api.Mul or api.AssertIsEqual build a constraint system. Later, the prover supplies a witness satisfying those constraints and produces a proof; the verifier checks the proof against the compiled relation.
This distinction matters for hints. A hint runs as ordinary Go during witness generation and gives the solver values that would be costly to derive inside the circuit. The verifier never runs that code. It only checks the constraints attached to the returned values, so a malicious prover can replace the hint output with any other values satisfying the same constraints.
gnark’s standard library includes emulated elliptic-curve arithmetic. Scalar multiplication computes , which normally requires processing every bit of . Classic GLV shortens this operation on curves with a cheap endomorphism. For curves of the form , a nontrivial cube root of unity gives the map:
Inside the prime-order subgroup, that map acts as multiplication by a fixed eigenvalue :
The scalar can then be split into two signed, roughly half-sized values satisfying:
where is the subgroup order. This turns one full multiplication into a joint multiplication:
The two shorter scalars are processed together, sharing the same doublings. The endomorphism is cheap, so the circuit saves constraints without asking the prover to supply the final result. This last point is the difference between classic GLV, used here by BLS12-381 and BW6-761, and the fake-GLV verification method from the earlier advisory.
Reference: the fake-GLV advisory#
The advisory I reviewed concerned P-256, P-384, and the STARK curve, which don’t have the cheap endomorphism needed by classic GLV. Their variable-base multiplication used fake GLV, with the prover supplying as a hint instead of computing . Outside the separately handled zero-scalar and infinity-input cases, the prover supplied short integers and signed . The circuit checked and
then checked
If and belong to the same prime-order group of order , this is sound. Since , it has an inverse modulo , and the checked equation implies . The missing prerequisite was an on-curve constraint for . Once an off-curve pair of coordinates is allowed into formulas that assume curve points, the group argument no longer applies, even though the circuit equations can still be satisfied.
That gap reached gnark’s ECDSA gadgets and P256Verify. A malicious prover could choose the off-curve contribution used in the verification equation and produce a proof for a signature that wasn’t made by the claimed private key. The fix added the missing curve-membership constraint, but affected circuits had to be recompiled and their proving and verification keys regenerated because the relation itself changed. Certora’s article, Take no hint: soundness vulnerability in gnark zk-SNARK library
, gives a more detailed walkthrough of hints, fake GLV, and the ECDSA forgery.
The diagram below summarizes how classic GLV and fake GLV use hints to compute or verify scalar multiplication:
Classic GLV
Start with the input
A point , a scalar , and a cheap endomorphism .
Hint a scalar split
Check the bounded signed values satisfy .
Compute inside the circuit
A joint loop processes the bits of and , sharing doublings.
Return the computed point
Correct loop arithmetic makes this the intended scalar multiple.
Fake GLV
Start with the input
A point and a scalar , without the cheap endomorphism used by classic GLV.
Hint the result
The prover supplies . Check short and signed , with and ; handle zero scalars and infinity inputs separately.
Verify a group relation
For and in the same required prime-order group, check:
Accept the supplied point
Inverting modulo makes that relation imply .
Okeyy perfect, but now what? Back to classic GLV, then. The circuit computes the point itself, so we’ll go a lil’ deeper: what does the arithmetic assume about its inputs, and where are those assumptions enforced?
My spider-sense is tingling#
What caught my eye in that classic-GLV branch was the warning above doubleAndAdd
. Its inputs must be nonzero and different from each other and each other’s inverse. The helper assumes that precondition on this path; it doesn’t assert it. From there, it was all about finding a split that passed the checks and still made the loop do what that comment said it shouldn’t. Good news, I’m usually good at breaking invariants :D
Let’s dive to see what actually reach it and what the prover can manipulate.
Circuit settings & the prover’s entry point#
BLS12-381’s parameters set PreferClassicGLV: true
. For a variable-base point, the default ScalarMul dispatch
selects scalarMulGLV.
The implementation supports signed subscalars. A hint returns two magnitudes and their sign bits, and the circuit range-checks the magnitudes and constrains their signed combination modulo .
The hint’s usual decomposition algorithm isn’t part of that constraint. The prover can supply a different bounded pair, as long as it satisfies the same relation. So the loop has to handle every accepted decomposition, including ones the stock solver wouldn’t choose.
A complete API with an incomplete loop#
The default ScalarMul API describes complete arithmetic. Here, complete means that the operation gives the correct group result for every input in its stated domain. For point addition, that includes equal points, inverse points whose sum is infinity , and infinity itself. A complete scalar multiplication also handles a zero scalar and an input at infinity.
Completeness can come from formulas that cover all those cases, or from explicit, constrained handling of the exceptional ones. In a circuit, the guarantee has to hold for every accepted witness, including alternative hint outputs.
An implementation can still use an incomplete formula internally if it proves that the formula’s preconditions always hold at that call. This requires a loop invariant, a property established at initialization and preserved by every update. For this loop, it must keep each helper’s inputs finite and its affine denominators nonzero, for every accepted scalar split. The decomposition relation alone doesn’t establish that property.
Inside scalarMulGLV, the merged loop
updates the accumulator like this:
// Acc = [4]Acc + T
Acc = c.double(Acc)
Acc = c.doubleAndAdd(Acc, T)
Each iteration consumes two bits from each subscalar and selects from a precomputed table. The first instruction doubles the accumulator; doubleAndAdd(p, q) then computes , giving the intended update.

But doubleAndAdd
uses incomplete affine formulas. For inputs , its first chord requires finite points with . Its second denominator also excludes . The surrounding doubling has its own requirement that the accumulator be finite and have nonzero . These are the prerequisites the invariant needs to preserve. The complete-mode AddUnified selection applies to the final low-bit corrections, not these loop calls.
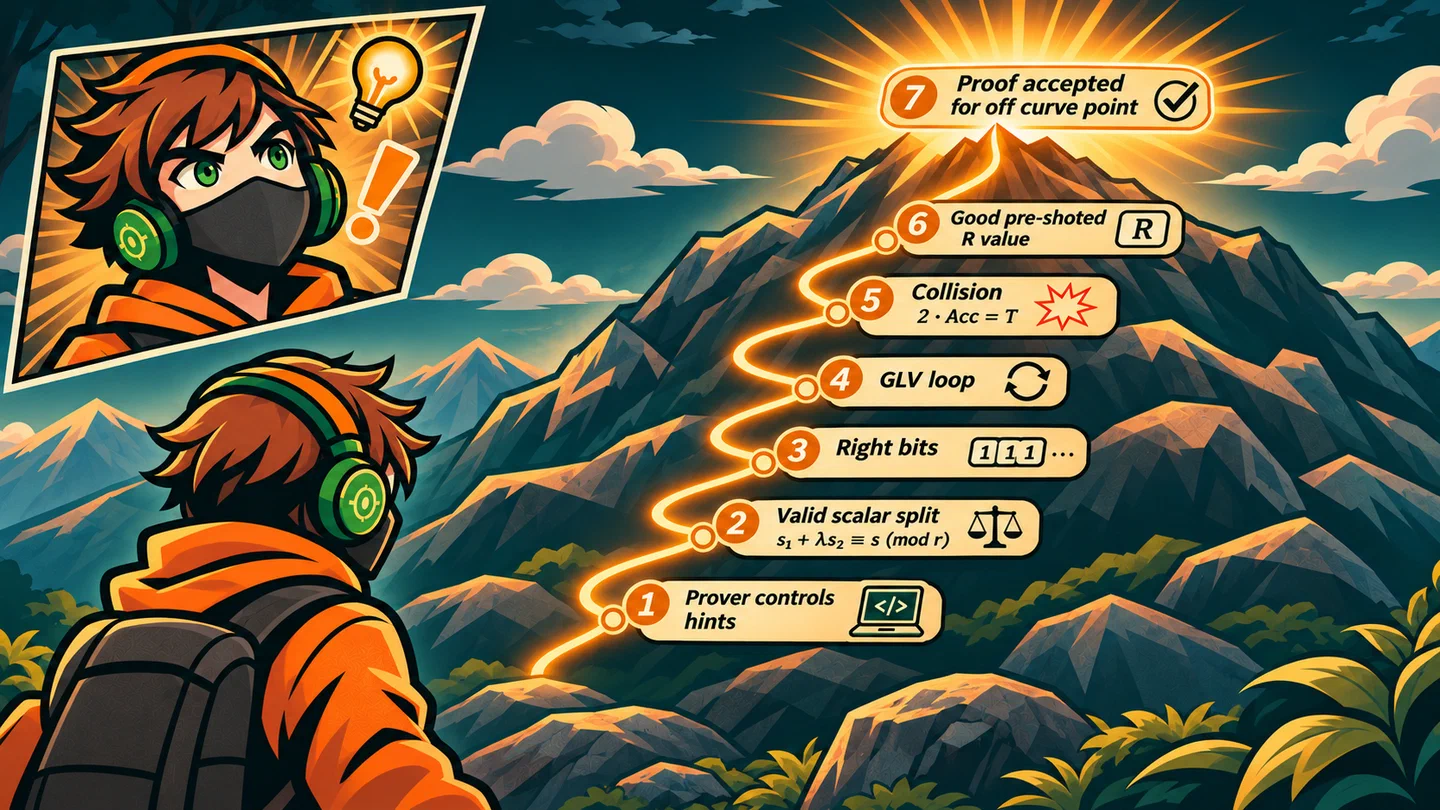
And as we’ve seen, equal inputs are enough to violate the helper’s precondition. Now, to reach them, the scalar bits need to make the first doubling land on exactly the point the table selects. Prepare yourself, it will be a long road…
Choosing the bits that make the points collide#
For BLS12-381, the configured eigenvalue is:
lambda = 228988810152649578064853576960394133503We’re gonna start with one accepted split and follow its bits ’till the two inputs meet.
1. Start with a split the circuit accepts
Choose the scalar and positive subscalars:
Both magnitudes fit the enforced 129-bit bounds, and is canonical. The decomposition relation holds exactly over the integers:
We’ll see how to get these values in the appendix . For now, just enjoy how they’ll break the invariant.
2. Start both accumulator coefficients at 1
Because both subscalars are positive, the initialization
uses and with their original signs. The input point is named Q in the code:
As the bits are read, track the coefficient of using , and the coefficient of using . A bit of 1 adds its base point after doubling; a bit of 0 subtracts it.
For either processed binary prefix , the corresponding coefficient is . Initially , so both coefficients are 1. This relation lets us recover the accumulator from the bits already processed.
Deriving the coefficient 2k + 1 from the loop
For either base point, let be its accumulator coefficient. The underlying single-bit step doubles , then adds 1 or subtracts 1 according to the bit :
Let be the ordinary binary prefix already read, meaning the integer represented by the bits processed so far. Before any bits are read, and , so . Appending a bit to that prefix changes it to . Applying the signed-bit update gives:
Each bit preserves . The merged update applies two such steps at a time, so the same relation holds after each merged iteration.
If you’d like a small exercise, write this as a proof by induction on the number of processed bits. The initial gives the base case, and the update above gives the induction step.
3. Pause just before the last merged iteration
Bits are numbered from 0 at the least significant end. The loop reads two bits per subscalar
, at positions i and i-1, then decreases i by two. Near the end, i = 4 consumes bits 4 and 3. At i = 2, bits 2 and 1 are next; bit 0 is reserved for the final conditional correction
, which subtracts the corresponding base point if that bit is 0.
At entry to i = 2, the processed prefixes therefore exclude the three lowest bits. Removing three binary positions means shifting right by three, or dividing by and rounding down. Both chosen subscalars end in 111, whose value is 7, so discarding those bits gives:
Substituting those prefixes into , the coefficients of and are:
The accumulator is now:
4. Two paths reach the same point
The current accumulator and the next bit pair determine the two inputs to doubleAndAdd separately.
Double the accumulator
The loop first computes .
Using , its coefficient is :Select the table point
At
i = 2, the selector readss1bits[2],s2bits[2],s1bits[1], ands2bits[1].
All four bits are 1, so each underlying step adds .Merging the two steps doubles the first contribution and adds the second.
The precomputed table entry is:
Calling that shared point , the next instruction becomes:
Acc = c.doubleAndAdd(U, U)Its inputs are equal, violating the incomplete helper’s precondition. The decomposition check accepted exactly the values needed to reach this forbidden input pair.
Niiiice, we’ve managed to give the helper exactly the input it asked us not to. Before following what happens to the coordinates, here’s a small Python check of the split, bounds, bits, and coefficient equality:
lam = 228988810152649578064853576960394133503
r = int(
    "73eda753299d7d483339d80809a1d80553"
    "bda402fffe5bfeffffffff00000001", 16
)

s = 9 * (lam + 1)
s1, s2 = 2 * lam + 9, 7

assert 0 < s < r
assert s1.bit_length() <= 129
assert s2.bit_length() <= 129
assert s1 + lam * s2 == s
assert ((s1 >> 1) & 3) == 3
assert ((s2 >> 1) & 3) == 3

A1 = 2 * (s1 // 8) + 1
A2 = 2 * (s2 // 8) + 1
assert A1 == (lam + 3) // 2
assert A2 == 1
assert 2 * (A1 + lam * A2) == 3 * (lam + 1)
When the slope stops being constrained#
The chosen bits have brought the loop to doubleAndAdd(U, U). The intended result is , but the helper’s first slope calculation assumes distinct points. For generic inputs and , it uses the chord formula:
assertedRatio
obtains from ratioHint and enforces:
where is the curve’s base-field modulus, distinct from the subgroup order .
With a nonzero denominator, that equation determines the ratio. With equal inputs , both coordinate differences vanish:
The constraint no longer determines a slope. Equal-point handling would need different formulas; continuing with this chord formula doesn’t implement the intended group operation.
The stock ratioHint
already handles a zero denominator by returning zero:
den := new(big.Int).Mod(in[1], p)
if den.Sign() == 0 {
    out[0].SetInt64(0)
    return nil
}
For this witness, the stock slope hint supplies zero, the constraint accepts it, and the remaining arithmetic produces an off-curve result. Both subscalars are odd, so the final low-bit selectors retain the loop result. The adversarial witness changes only the GLV decomposition; the standard slope hint supplies everything else.
The malformed point survives the EIP-2537 wrapper#
That off-curve value survives the low-bit corrections and becomes the ScalarMul output. Now let’s see whether the wrapper lets it through too. For BLS12-381, we can trace it to the public expected result through the exported ECG1ScalarMulSumBLS
gadget. This wrapper accumulates a scalar multiplication as part of the operation defined by EIP-2537’s G1 MSM precompile
.
Its relevant statements are:
g1.AssertIsOnG1(P)
res := curve.ScalarMul(P, s)
sum := curve.AddUnified(prev, res)
g1.AssertIsEqual(sum, expected)
AssertIsOnG1(P) validates the input’s subgroup membership. The wrapper then binds the computed result to expected through coordinate equality, with no membership constraint on either result.
With prev = (0, 0), the normal initial accumulator and infinity representation, AddUnified forwards the malformed result. Supplying those coordinates as expected satisfies the final equality, so the malformed value becomes the public EIP-2537 output accepted by the circuit.
Summary of the attack surface & other dispatch paths#
Now that we’ve got the pattern and the full attack path in mind, let’s see where else we can weaponize this primitive.
But first, just a reminder of what we’ve got:
With , , and the claimed output public, standard Groth16
Setup,Prove, andVerifyproduce and accept a proof for an off-curve result different from native . The BLS12-381 circuit callsECG1ScalarMulSumBLS.
During private witness generation, the malicious prover chooses a constraint-valid GLV decomposition that drives the fixed circuit into
doubleAndAdd(U, U), with a valid input point and canonical scalar. The circuit and verification key stay unchanged, the proving parameters are generated honestly, and the verifier runs normally. Every constraint is satisfied, so the forged witness produces a standard proof that verifies.
Digging, digging… Aaaaand yep! BW6-761 takes us back to the same weak spot with its own curve parameters. Like BLS12-381, it sets PreferClassicGLV: true and reaches the same loop. A separate signed decomposition within its 189-bit bounds makes the final doubleAndAdd receive equal points.
Okey, now from this, since the pattern repeat on BW6-761, I reported it immediately and signaled to the gnark team about arithmetic primitives for similar unchecked assumptions.
For secp256k1 and BN254, though, the variable-base dispatch takes us elsewhere. Their parameters provide efficient-endomorphism constants but leave PreferClassicGLV at its default value, false, so ScalarMul selects scalarMulGLVAndFakeGLV after the fixed-base-comb fast path. That routine always constrains its hinted result to lie on the curve. In the default complete mode, it also uses AddUnified and the unified doubling variant instead of the incomplete doubleAndAdd loop reached by classic GLV.
My confirmed cases covered variable-base G1 multiplication on BLS12-381 and BW6-761. The team’s published advisory
lists a wider surface through ScalarMul, ScalarMulBase, JointScalarMul, and MultiScalarMul, including callers in emulated KZG, PLONK, and Groth16 recursion over these curves.
Compile-time constant points route to the fixed-base comb path only when precomputation succeeds , which requires a finite on-curve point of order ; otherwise they fall back to the variable-base dispatch.
G2 uses separate gadgets, but the same advisory also covers a distinct BW6-761 G2 subgroup-check issue found during the review.
Patching & Keeping the optimization with a torsion offset#
The repair starts where this chain begins, at the exceptional addition inside the scalar-multiplication loop. Complete arithmetic can handle that case directly. Keeping the optimized incomplete formulas requires establishing that no accepted witness can reach their exceptional inputs.
In the report, I suggested a fixed nonzero odd-order torsion offset in the accumulator for subgroup-validated inputs, with order 3 for BLS12-381 and order 127 for BW6-761.
The gnark team confirmed & published GHSA-4g5f-3gmm-9q87 with High severity and released the fix in gnark v0.16.5 . The implementation follows this direction in
ecbe370: the offset supplies the invariant the incomplete loop needs, because the accumulator carries a component that no lookup point can cancel.
As a note: the review turned up other soundness bugs too, in BW6-761 G2 subgroup checks, opt-in incomplete arithmetic, and native BLS12-377 and Grumpkin primitives. Those were fixed in the same release.
Kudos to Dickson Wu
for reporting the missing input-subgroup check in classic GLV, and to LeonPaulSchneider
for the Grumpkin ScalarMul forgery. The patch now enforces input-subgroup membership by default in classic GLV, which supplies the premise for the offset argument below.
A bit of group theory to understand the torsion-part fix#
Let be the prime-order subgroup of order , with . Choose a fixed valid curve point of exact odd order , where or for the respective curves. Since , the two subgroups share only infinity:
Put into the accumulator at initialization, while keeping the lookup table in . At each loop entry, the accumulator then has the form
Initially . The intended group update gives , because contributes no torsion component. A single-bit update multiplies it by 2 instead. Thus remains a power of 2. No such power is divisible by the odd order , so the offset component never vanishes. We still need to check that the affine formulas safely implement these group updates.
Immediately before doubleAndAdd, the loop doubles the accumulator. The helper receives
If the scalar bits could make , then
The left side belongs to , and the right side belongs to . Their common value would have to be , contradicting the nonzero offset. Replacing with gives the same contradiction. The inputs therefore have different -coordinates, so the first chord denominator can’t be zero.
The same argument keeps and away from infinity and points of order 2, since doubling preserves a nonzero torsion component. The standalone doubling therefore has a nonzero denominator too.
The table points are nonzero as well. Each is with . For these curves, . If , substituting would give
But , so this is impossible. Since has order , every selected is nonzero.
Finally, the helper’s second denominator is . The first chord is already valid, so is finite. Equal -coordinates would mean , giving either or . The table excludes the first case. The second would require canceling , which is impossible by the same subgroup argument.
This closes the induction. Starting from a valid initialization with , the invariant makes each formula valid, and its output preserves the invariant for the next iteration. Choosing different subscalars, including their signs, changes and within . It can’t change this separation between the accumulator and the table.
The argument relies on the input being constrained to the prime-order subgroup, with infinity handled separately, and on having the stated exact order. Only the accumulator receives the offset. In particular, the lookup entry T2 := Acc
must retain the unshifted value.
The low-bit corrections add or subtract subgroup points, leaving the tracked torsion component unchanged. The bit recurrence and constrained scalar split therefore give
Removing the known final offset with complete addition recovers , including when that result is infinity.
Impact#
The advisory’s impact assessment includes forged precompile results, signature or commitment checks, and recursive proof verification, depending on how the affected arithmetic is used.
For example, with the EIP-2537 path we’ve followed, a validity system relying on this gadget to enforce precompile execution could accept an invalid execution trace and state root. That last step depends on the integration; the result established here is the accepted proof for a false G1MSM output.
TL;DR & Conclusion#
gnark’s classic-GLV loop relied on an arithmetic precondition that a constraint-valid scalar split could violate.
- My reproduced cases: variable-base BLS12-381 G1 and BW6-761 G1 multiplication, including the BLS12-381 EIP-2537 G1 MSM gadget
- Weak point: equal inputs to
doubleAndAddleave its first slope unconstrained. An off-curve result passes the circuit, and its Groth16 proof verifies with honestly generated keys - Impact: forged group results can undermine precompile execution, signature or commitment checks, and recursive verification, depending on the application
- Patch: a fixed odd-order torsion offset, with input-subgroup checks, keeps the accumulator away from the loop’s exceptional inputs
My personal thought: this one really felt like a juicy chall’ from the old golden age moment in past CTFs. Overall, that was everything about the code comment giving me an assumption to poke at, and the whole puzzle became constructing a bad input while keeping every constraint happy and me trying to push it ’till it worked.
Appendix: how to pre-shot a collision and generalize it#
The split used in the walkthrough
is one member of a larger family. For the BLS12-381 G1 loop in v0.16.4, we can construct at least 32 signed decompositions, including that example, that make doubleAndAdd receive two equal subgroup points. All 32 collide at the last merged iteration, i = 2.
We’ll keep the classic-GLV notation for the public scalar , point , endomorphism , eigenvalue , and subgroup order . Assume is nonzero and belongs to that prime-order subgroup.
Write the collision condition in terms of bits#
To include the signed decompositions , write each component , for , in terms of its magnitude and sign :
Here correspond to the code’s s1, s2; the point-sign selection
gives the bases and .
Let denote bit position of , using the bit numbering from the walkthrough . The signed-bit update contributes to its signed base point.
For a merged iteration indexed by its higher bit , the pair gives a lookup digit for each component through the merged-step identity :
| Bits | Digit |
|---|---|
00 | |
01 | |
10 | |
11 |
The table lookup combines these digits into , the point passed as the helper’s second argument:
Let be the already-read prefix of before iteration . For the current , its value is
Let be the accumulator at entry to iteration , before its first doubling. The relation from the walkthrough applies to both signed base points, giving
The two input paths collide when . Expressing both points as multiples of gives
From equal point inputs to the scalar congruence
Doubling the accumulator doubles each base-point coefficient. For either component, , so
For the inputs to be equal, subtracting must give the point at infinity, . The lookup contributes coefficient for each base point, so subtracting it gives
Now use the endomorphism relation , . The second term becomes . Both terms multiply the same point, so their coefficients add.
Since has exact order , that sum represents precisely when its coefficient is divisible by . This gives the congruence above. The coefficient doesn’t have to be zero as an integer; the next section uses the bounds to narrow down its possible multiples of .
For each component, call the doubled prefix coefficient minus its lookup digit . Also write for the relative sign of the two components. Multiplying by , whose square is 1, reduces the condition to
Here means the components have the same sign, and means their signs differ.
Interesting point: why can’t the earlier iterations (i > 2) collide?#
For BLS12-381, the configured eigenvalue and subgroup order satisfy
The loop setup visits even indices from 128 down to 2. At any , the prefix formula removes at least five low bits. Together with the possible lookup digits, this gives
Where the prefix and coefficient bounds come from
The largest allowed magnitude is . At , dividing by leaves at most
Earlier iterations divide by a larger power of two, so the same upper bound still holds. To bound , take the smallest prefix and largest digit for its minimum, then the largest prefix and smallest digit for its maximum:
The configured value of is larger than , so this upper bound is strictly below . The lower bound is only , which also gives .
Call the integer on the left of the collision congruence . Then
Why the whole expression is smaller than r
The two terms in may have different signs. The triangle inequality bounds their sum regardless of those signs:
Since and , the second absolute value is . Both are below , so the sum is below . The identity puts that bound one unit below .
The only multiple of in that interval is zero, so a collision would require over the integers. But is odd and can’t be zero. Hence , while , and the terms can’t cancel.
Why the modular condition forces an impossible equality
The congruence means for some integer . Since , we have , leaving only . Rearranging gives the required equality.
Now subtracts an odd lookup digit from an even number, so it is odd. In particular, and . Multiplying by gives
For cancellation, would need that same absolute value. Its bound rules that out for either choice of .
That leaves only i = 2.
Solve the last merged iteration#
At i = 2, the prefix bound becomes , giving
The same expression now satisfies
This interval allows the multiples . Parity removes the first and last. Both and are odd, so is even, whereas is odd. Once again, the congruence must be the integer equality
Why the last iteration still forces L = 0
At , the prefix drops three low bits instead of at least five. Its maximum is now
Putting this into the same coefficient formula gives ; its minimum stays . The triangle inequality therefore gives
For the configured , we have . The bound is therefore below . Unlike the earlier iterations, this leaves room for .
Parity rules those out. Each is odd, so is odd too. Adding two odd integers gives an even , including when one term is negative. But is odd, so neither nor can equal . Only zero remains.
The bounds now restrict to or 1 and force . Every solution therefore satisfies
How the bounds leave only these two coefficient values
Taking absolute values in gives . Since , dividing by the positive leaves . Its oddness leaves only .
Substituting either value gives . The lower bound excludes , so . The equality then becomes , or .
For the first component, substituting the definition of gives
Because , this is an integer only for or 3. For the second component, forces , with digit 3 for equal signs and digit 1 for opposite signs. This gives four patterns we can use.
Why these are the four prefix-and-digit patterns
For to be an integer, its numerator must be divisible by four. Using ,
We therefore need . Among the four lookup digits, only and 3 qualify. Substituting each gives the two listed prefixes for .
For the second component, . If , even the largest digit would give , contradicting . Thus , leaving . This is 3 for equal signs and 1 for opposite signs. Either second-component choice combines with either first-component choice, giving the four rows.
Turn the four patterns into 32 signed pairs#
The prefixes and lookup digits fix every magnitude bit except bit zero. Write that remaining bit as . Reassembling the magnitude gives
For , the two prefix-and-digit choices yield and . For , they yield when , or when .
Choose the first component’s sign . The second sign is then . Call the point passed as both helper inputs . Substituting into the four patterns gives the following families.
| Family | Signed | Signed | Collision point |
|---|---|---|---|
| A | |||
| B | |||
| C | |||
| D |
Working through one row of the family table
Take the first pattern, which becomes family A. Substituting and into the magnitude formula gives
Its second component has and , giving . Since , both components have sign . The lookup point is then
The other rows follow by substituting their prefixes, lookup digits, and relative signs into these same formulas.
Each row allows two choices for each and two choices for , giving eight signed pairs per row and 32 distinct pairs overall. All magnitudes fit the 129-bit bounds. Each chosen pair determines its public scalar through
Family B with recovers the original example .
The values don’t appear in , because bit zero hasn’t been processed when the collision occurs. Changing both component signs negates . For any fixed family and sign, the four bit-zero choices reach the same internal collision point.
Follow bit zero through to the public output#
Those four choices can still produce different final coordinates. Write over the coordinate field .
Note: each multiplier of in the family table is nonzero modulo , so has order . Thus : a finite point with has order 2, and on this curve gives order 3.
Substituting the stock hint’s zero slope into the remaining helper formulas gives the following ratio and immediate loop output :
Where the ratio and the coordinates of R0 come from
At the collision, both helper inputs are , and its first slope is zero. The helper’s temporary coordinate
, named x2 in the code, is therefore
The next ratio uses numerator and denominator , giving
Here is the value stored in the helper’s λ2 after adding the zero first slope. That name comes from its negative-second-slope formula and is unrelated to the GLV eigenvalue .
If denote the returned coordinates, substituting into the last two formulas gives
These are the coordinates of . This substitution follows the circuit’s field arithmetic after its exceptional input; it doesn’t assume the returned pair is a valid curve point.
We can check against the curve equation : here, a finite point must satisfy . Substituting its coordinates and using and , we get
Since , the result is nonzero, so is off curve before either low-bit correction.
The two low-bit corrections
then act in order. Let denote the exact AddUnified coordinate formula
, including its selectors. Call the value after the first correction :
The second correction gives , the final coordinates compared with the public expected result:
Why bit zero selects R1 and the final result this way
The correction is designed for the odd-prefix encoding . With valid loop arithmetic, the coefficient after processing every bit above position zero would be for the signed base point. The desired magnitude is . Subtracting one copy of that signed base point when removes the difference; a bit of 1 needs no correction.
For the first component, that signed base point is . The code computes the correction candidate , then Select(s1bits[0], ...) keeps for a bit of 1 or chooses that candidate for a bit of 0. The selected coordinates are .
The second component works on this selected , using signed base point . Its correction candidate is . The second selector keeps when and chooses the candidate when , producing .
The order matters. If the first correction changes the coordinates, the second formula receives those changed coordinates. With , both selectors keep their input, so the final result is simply .
Once is off curve, these corrections must be followed as coordinate arithmetic. Abstract group addition assumes valid curve points and can’t describe what the circuit does with this malformed operand.
With the standard BLS12-381 G1 generator as , all 32 reproduced cases had a final public output off curve and different from native , and a Groth16 proof for each verified with honestly generated keys.
Kudos for the curious one that arrived here btw :D